[영화리뷰 감성분류][모델최적화]마지막 시도, 그리고 반성
[모델최적화]TAPT, WeightedModelEnsemble
Introduction
- tapt적용
- 전체데이터에 대해서 5개모델 다시 학습 후 앙상블 → 시간부족으로 못해봄
- 전체데이터셋으로 학습시킨 모델 효과있는지 실험→ 시간부족으로 못해봄
- 5개모델 acc를 Weight로 줘서 앙상블
- 역번역증강 사용할지 말지 결정 → 번역의 품질이 안좋아서 결국엔 사용 x
저번실험까지 해서 기껏 하이퍼파라미터 튜닝을 해뒀는데 TAPT라는 새로운 기법에 대해 알게됐다. 일반적으로 BERT모델을 내가 원하는 TASK에 FineTuning하는 기법인데, 이 기법을 사용하면 성능이 일반적으로 향상된다고 한다. 이 기법을 하이퍼파라미터 튜닝을 한 후에 알게되어서, 대회 종료까지 2일 남은 시점에서, 다시 하이퍼파라미터 튜닝을 해야하는 상황에 처해졌다. 따라서 TAPT를 일단 적용해보고, 기존에 찾았던 하이퍼파라미터를 이용해서 성능을 테스트해보기로 했다.
그 외에도 모델마다 acc성능이 다르므로, 추론단계에서 모델을 앙상블 할때 그냥 logit을 softvoting하는게 아니라, 모델간의 acc를 가중치로 줘서 softvoting하는 방법을 구현했다.
역번역 증강은 코드까지는 구현했으나, 강한부정, 강한긍정에서는 어느정도 문맥이 유지되는듯 했는데, 약한긍정, 약한부정을 역번역하니, 문맥이 아예 다른 데이터들이 생성되는것을 확인했다. 더 정교한 모델을 사용하면, 역번역 증강을 사용해서 데이터를 효율적으로 늘릴 수 있겠으나, 데이터를 늘리더라도, 최적의 하이퍼파라미터를 다시 학습하는데에는 시간이 없으므로, 역번역 증강은 이번대회에서는 사용하지 않기로 했다.
기존의 방식은 Traindata를 valid,train으로 다시 나눠서 학습용과 검증데이터를 나눠서 학습을 진행했다. 하지만 일반적으로 최종 모델을 학습할떄는 전체 데이터에 대해서 다시 학습한 후 앙상블을 한다고 한다. 이또한 앙상블을 하려면 최소 3개의 모델을 전체 데이터에 대해서 다시 학습을 해야하는데, 코드까지는 구현했으나, 시간부족으로 모델로 반영하지는 못했다.
Weighted Model Ensemble
# === Ensemble Inference Block (Weighted Averaging) ===
# Replace the original inference cell (ID: 079c8f40) with this code.

import torch
import numpy as np
import os
from tqdm.auto import tqdm # Import tqdm for progress bar
from transformers import AutoTokenizer, AutoModelForSequenceClassification, Trainer, TrainingArguments, DataCollatorWithPadding
import shutil # Import shutil for directory removal

print(f"현재 디바이스: {device}")

# --- Load Test Data ---
df_test = pd.read_csv("data/test.csv")
print(f"테스트 데이터 로드 완료: {len(df_test)} 샘플")

# --- Apply Preprocessing ---
# Use the 'preprocessor' instance fitted during training
print("테스트 데이터에 전처리 파이프라인 적용 중...")
test_texts = df_test["review"].tolist()
# Use transform only, assumes preprocessor is already fitted
# Ensure the preprocessor was fitted during the training phase
if not preprocessor.is_fitted:
    # If the preprocessor wasn't fitted (e.g., running inference separately),
    # you might need to fit it here or load a saved preprocessor state.
    # For now, we'll just apply basic preprocessing.
    print("Warning: Preprocessor가 fit되지 않았습니다. 기본 전처리만 적용합니다.")
    test_processed = preprocessor.basic_preprocess(test_texts)
else:
    test_processed = preprocessor.transform(test_texts) # Apply transform including rare word removal if fitted
print("테스트 데이터 전처리 완료")

# --- List of Trained Model Paths ---
# Ensure these paths match where models were saved in the training block
# 수정: best_model 대신 swa_model 경로를 사용하도록 변경
model_names = [
    "./tapted_klue_roberta_base",
    "./tapted_klue_bert_base",
    "./tapted_kykim_bert_kor_base",
    "./tapted_beomi_kcbert_base",
    "./tapted_koelectra_base_v3"
]
model_paths = [
    f"./results_{model_name.split('/')[-1].replace('-', '_')}/swa_model_{model_name.split('/')[-1].replace('-', '_')}" # <-- swa_model 로 변경
    for model_name in model_names # Use the same model_names list from training
]
print(model_paths)

# model_paths = [
#     f"./results_{model_name.split('/')[-1].replace('-', '_')}/best_model_{model_name.split('/')[-1].replace('-', '_')}" # <-- swa_model 로 변경
#     for model_name in model_names # Use the same model_names list from training
# ]

# --- Define Model Weights (Based on Validation Performance) ---
# 각 모델의 검증 데이터셋 F1 score (또는 Accuracy) 값으로 반드시 교체해야 합니다.
# 이거 f1으로 할지 accuracy로할지 둘다 해보기
# model_paths 리스트의 모델 순서와 동일하게 값을 넣어야 합니다.
model_performance_scores = {
    model_paths[0]: 0.8114, #roberta
    model_paths[1]: 0.8056, # 예시: tapted_klue_bert_base SWA 모델의 검증 F1
    model_paths[2]: 0.8179, # 예시: tapted_kykim_bert_kor_base SWA 모델의 검증 F1
    model_paths[3]: 0.7961,  # 예시: tapted_beomi_kcbert_base SWA 모델의 검증 F1
    model_paths[4]: 0.8077 #koelectra
    # 다른 모델 추가 시 여기에 성능 점수 추가
}

# --- Ensemble Inference ---
all_logits = []
successful_model_paths = [] # 추론에 성공한 모델 경로 저장
print("\n" + "=" * 50)
print("앙상블 추론 시작...")
print("=" * 50)

for model_path in tqdm(model_paths, desc="모델별 추론 진행"):
    if not os.path.exists(model_path):
        print(f"Warning: 모델 경로를 찾을 수 없습니다: {model_path}. 이 모델을 건너뜁니다.")
        continue

    print(f"\n모델 로딩: {model_path}")
    try:
        # Load tokenizer and model for the current path
        current_tokenizer = AutoTokenizer.from_pretrained(model_path)
        current_model = AutoModelForSequenceClassification.from_pretrained(model_path)
        current_model.to(device)
        current_model.eval()

        # Create test dataset with the current tokenizer
        test_dataset_current = ReviewDataset(
            pd.Series(test_processed), # Pass processed text as a Series
            None, # No labels for test set
            current_tokenizer,
            CHOSEN_MAX_LENGTH
        )

        # Define minimal TrainingArguments for prediction
        temp_output_dir = f"./temp_prediction_{os.path.basename(model_path)}"
        predict_args = TrainingArguments(
            output_dir=temp_output_dir,
            per_device_eval_batch_size=BATCH_SIZE_EVAL * 2, # Increase batch size for faster inference
            dataloader_num_workers=2,
            remove_unused_columns=False, # Keep columns needed by dataset
            fp16=torch.cuda.is_available(),
            logging_steps=len(test_dataset_current) // (BATCH_SIZE_EVAL * 2) + 1 # Reduce logging
        )

        # Initialize Trainer for prediction
        pred_trainer = Trainer(
            model=current_model,
            args=predict_args,
            # tokenizer=current_tokenizer, # Trainer에서는 tokenizer 없어도 됨
            data_collator=DataCollatorWithPadding(tokenizer=current_tokenizer),
        )

        # Get predictions (logits)
        print(f"모델 추론 중: {model_path}")
        predictions = pred_trainer.predict(test_dataset_current)
        logits = predictions.predictions # Logits are in predictions.predictions
        all_logits.append(logits)
        successful_model_paths.append(model_path) # 성공한 모델 경로 추가
        print(f"모델 추론 완료: {model_path}")

        # Clean up memory
        del current_model
        del current_tokenizer
        del pred_trainer
        if torch.cuda.is_available():
            torch.cuda.empty_cache()
        # Clean up temporary directory
        if os.path.exists(temp_output_dir):
             shutil.rmtree(temp_output_dir)

    except Exception as e:
        print(f"Error during inference for model {model_path}: {e}")
        # Decide whether to continue or stop if one model fails
        # continue # 오류 발생 시 해당 모델 건너뛰기

# --- Weighted Averaging Logits ---
if not all_logits:
    raise ValueError("추론 결과가 없습니다. 모델 경로 또는 추론 과정을 확인하세요.")

print("\n로짓(logits) 가중 평균 계산 중...")
# Convert list of numpy arrays to a numpy array for easier calculation
all_logits_np = np.array(all_logits)

# Filter performance scores for successfully loaded models
relevant_scores = [model_performance_scores[path] for path in successful_model_paths if path in model_performance_scores]

if len(relevant_scores) != all_logits_np.shape[0]:
    print(f"Warning: 추론된 모델 수({all_logits_np.shape[0]})와 유효한 성능 점수 개수({len(relevant_scores)})가 다릅니다. 단순 평균을 사용합니다.")
    # Fallback to simple mean if weights don't match (e.g., model failed or score missing)
    average_logits = np.mean(all_logits_np, axis=0)
else:
    # Calculate weights based on performance scores (Normalization)
    total_score = sum(relevant_scores)
    if total_score == 0: # Avoid division by zero if all scores are 0
        print("Warning: 모든 모델 성능 점수가 0입니다. 동일 가중치를 사용합니다.")
        weights = np.ones(len(relevant_scores)) / len(relevant_scores)
    else:
        weights = np.array([score / total_score for score in relevant_scores])
    print(f"사용된 모델 경로: {successful_model_paths}")
    print(f"해당 모델 가중치: {weights}")

    # Calculate the weighted average logits across models (axis=0)
    average_logits = np.average(all_logits_np, axis=0, weights=weights)

print(f"가중 평균 로짓 계산 완료. 형태: {average_logits.shape}")

# --- Final Prediction ---
predicted_labels = np.argmax(average_logits, axis=1)
print(f"최종 예측 레이블 생성 완료: {len(predicted_labels)}개")

# --- Add predictions to the test DataFrame ---
df_test["pred"] = predicted_labels
print(f"\ndf_test에 pred 컬럼이 추가되었습니다. 형태: {df_test.shape}")

# --- Analyze Prediction Distribution ---
unique_predictions, counts = np.unique(predicted_labels, return_counts=True)
print("\n최종 예측 분포:")
# Ensure LABEL_MAPPING is defined in your environment
if 'LABEL_MAPPING' not in globals():
    LABEL_MAPPING = {0: "강한 부정", 1: "약한 부정", 2: "약한 긍정", 3: "강한 긍정"} # Define if not present

for pred, count in zip(unique_predictions, counts):
    percentage = (count / len(predicted_labels)) * 100
    class_name = LABEL_MAPPING.get(pred, f"클래스 {pred}")
    print(f"   {class_name} ({pred}): {count:,}개 ({percentage:.1f}%)")

print("\n" + "=" * 50)
print("앙상블 추론 완료!")
print("=" * 50)

# GPU 메모리 정리
if torch.cuda.is_available():
    torch.cuda.empty_cache()

# Note: The code for creating and saving the submission file remains the same
# It should follow this block, using the df_test DataFrame which now has the 'pred' column
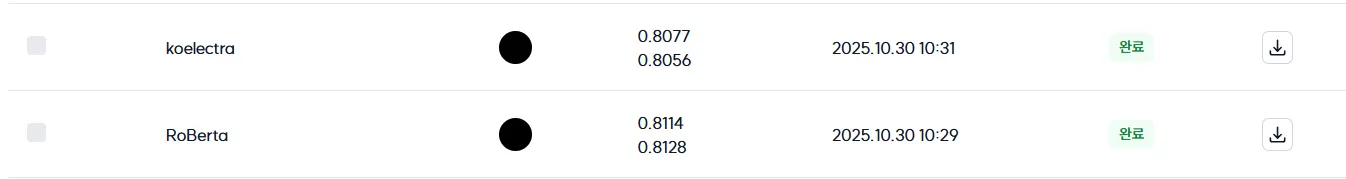
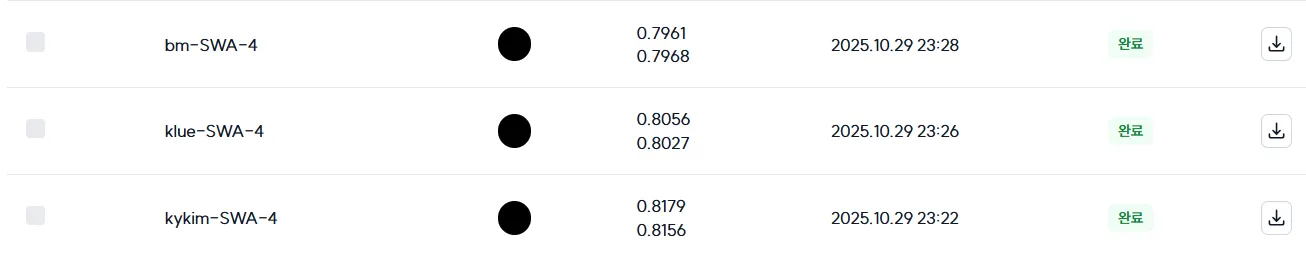
최종 목표가 test/acc를 향상시키는 것인만큼 각 모델의 가중치는 각 단일모델의 test/acc를 확인하고, 이 acc를 정규화 한 후 가중치로 사용했다.
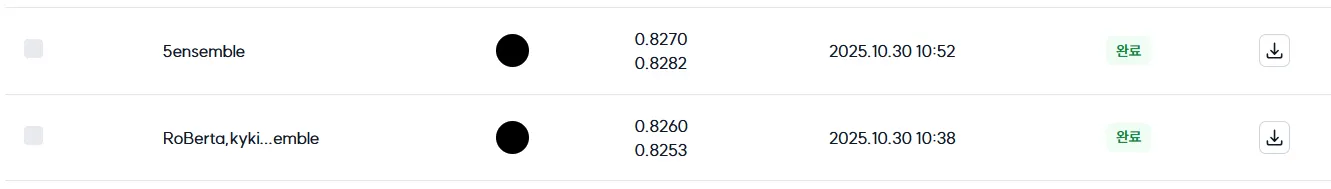
단일모델로서 가장 성능이 잘나왔던 RoBERTa와 Kykim-BERT두개를 앙상블한것보다, 전체 모델 5개를 앙상블한 결과가 더 성능이 잘나오는 것을 확인할 수 있었다. Bagging에 의해 서로다른 모델을 사용하면 일반적으로 선형적으로 성능이 향상됨을 확인할 수 있었다.
전체 데이터를 이용한 학습
# === 최종 모델 재학습 (전체 데이터 활용) 블록 ===
# 이 블록은 앙상블 훈련(ID: 176174ee) 이후에 실행합니다.

import pandas as pd
import torch
from transformers import AutoTokenizer, AutoModelForSequenceClassification, TrainingArguments, DataCollatorWithPadding, Trainer
import os
import shutil # 추가: 디렉토리 관리용

print("\n" + "="*60)
print("🚀 전체 데이터(학습+검증)를 사용한 최종 모델 재학습 시작")
print("="*60 + "\n")

# --- 설정값 ---

# 1. 재학습할 기반 모델 이름 및 경로 선택
#    !!! 중요: 초기 훈련/검증에서 가장 좋은 성능을 보인 모델의 이름을 지정하세요.
#    (예: Wandb 로그에서 eval_loss가 가장 낮거나 eval_f1/eval_accuracy가 가장 높았던 모델)
#    SWA 모델이 더 좋았다면 해당 모델 경로를 initial_model_path로 직접 지정해도 됩니다.
BEST_PERFORMING_MODEL_NAME = "./tapted_kykim_bert_kor_base" # <--- 실제 최적 모델 이름으로 변경하세요 (예시)
best_model_short_name = BEST_PERFORMING_MODEL_NAME.split('/')[-1].replace('-', '_')

# 초기 훈련 결과에서 'best_model' 경로를 사용합니다.
# SWA 모델을 기반으로 재학습하려면 이 경로를 swa_model 경로로 변경하세요.
# initial_model_path = f"./results_{best_model_short_name}/best_model_{best_model_short_name}"
# 예: SWA 기반 재학습 시
initial_model_path = f"./results_{best_model_short_name}/swa_model_{best_model_short_name}"

print(f"선택된 기반 모델: {BEST_PERFORMING_MODEL_NAME}")
print(f"기반 모델 경로: {initial_model_path}")

if not os.path.exists(initial_model_path):
    raise FileNotFoundError(f"기반 모델 경로를 찾을 수 없습니다: {initial_model_path}. 경로를 확인하거나 이전 훈련을 완료하세요.")

# 2. 전체 데이터 재학습 시 사용할 에포크 수
#    !!! 중요: 초기 훈련 중 검증 데이터에서 최적 성능(예: 가장 낮은 eval_loss)을 보였던
#    에포크 수를 확인하여 설정하세요. (Wandb 등 로그 확인 필요)
FINAL_TRAIN_EPOCHS = 5 # <--- 실제 최적 에포크 수로 변경하세요 (예시)
print(f"재학습 에포크 수: {FINAL_TRAIN_EPOCHS}")

# 3. 최종 모델을 저장할 디렉토리 경로
final_output_dir = f"./final_model_{best_model_short_name}_fulldata"
print(f"최종 모델 저장 경로: {final_output_dir}\n")

# 4. 사용할 하이퍼파라미터 (초기 훈련의 최적값 유지)
#    이 값들은 이전 셀(ID: b5ba58df) 및 훈련 루프(ID: 176174ee)에서 사용된 값과 동일해야 합니다.
FINAL_LEARNING_RATE = LEARNING_RATE
FINAL_WEIGHT_DECAY = WEIGHT_DECAY
FINAL_WARMUP_STEPS = WARMUP_STEPS
FINAL_BATCH_SIZE_TRAIN = BATCH_SIZE_TRAIN
FINAL_GRAD_ACCUM_STEPS = 4 # 초기 훈련과 동일하게 설정 (training_args에서 확인)
FINAL_LABEL_SMOOTHING = 0.03442149572139974 # 초기 훈련 값 (training_args에서 확인)
FINAL_LR_SCHEDULER = "constant" # 초기 훈련 값 (training_args에서 확인)
# Focal Loss 파라미터 (CustomTrainerWithFocalLoss 초기화 시 사용된 값)
FINAL_FOCAL_ALPHA = [1,1,1,1]
FINAL_FOCAL_GAMMA = 4.194768435552584

# --- 1. 학습 + 검증 데이터 합치기 ---
print("📊 학습 데이터와 검증 데이터 합치는 중...")
# train_data와 val_data는 이전 데이터 분할 셀(ID: e6e4ca17)에서 생성된 변수입니다.
if 'train_data' not in globals() or 'val_data' not in globals():
    raise NameError("train_data 또는 val_data 변수를 찾을 수 없습니다. 이전 데이터 분할 셀을 실행했는지 확인하세요.")

full_train_data = pd.concat([train_data, val_data], ignore_index=True)
print(f"   전체 학습 데이터 크기: {len(full_train_data):,}개")
print(f"   합쳐진 데이터 샘플 확인 (처음 3개):\n{full_train_data.head(3)}\n")

# --- 2. 기반 모델 및 토크나이저 로드 ---
print(f"🔩 기반 모델 및 토크나이저 로딩: {initial_model_path}")
try:
    final_tokenizer = AutoTokenizer.from_pretrained(initial_model_path)
    final_model = AutoModelForSequenceClassification.from_pretrained(
        initial_model_path,
        num_labels=NUM_CLASSES, # 클래스 수는 동일
    )
    final_model.to(device) # GPU로 이동
    print("   모델 로딩 완료.")

    # 특수 토큰 추가 및 임베딩 리사이즈 (초기 훈련과 동일하게 수행)
    num_added = final_tokenizer.add_tokens(NEW_SPECIAL_TOKENS)
    if num_added > 0:
        final_model.resize_token_embeddings(len(final_tokenizer))
        print(f"   {num_added}개의 특수 토큰 추가 및 임베딩 리사이즈 완료.")

except Exception as e:
    print(f"❌ 모델 로딩 중 오류 발생: {e}. 재학습을 중단합니다.")
    # 필요한 경우 여기서 중단
    raise e

# --- 3. 전체 데이터셋 생성 ---
print("\n📚 전체 데이터에 대한 PyTorch 데이터셋 생성 중...")
# ReviewDataset 클래스는 이전 셀(ID: 1751489f)에 정의되어 있어야 합니다.
full_train_dataset = ReviewDataset(
    full_train_data["review"],  # 합쳐진 데이터의 전처리된 리뷰 사용
    full_train_data["label"],   # 합쳐진 데이터의 레이블 사용
    final_tokenizer,
    CHOSEN_MAX_LENGTH,
)
print(f"   전체 데이터셋 생성 완료: {len(full_train_dataset):,}개")

# --- 4. 훈련 설정 (TrainingArguments) 변경 ---
#    - 검증(evaluation) 비활성화
#    - 최적 모델 로딩 비활성화
#    - Wandb 로깅 비활성화 (선택 사항)
print("\n⚙️  최종 훈련을 위한 TrainingArguments 설정 중...")
final_training_args = TrainingArguments(
    output_dir=final_output_dir,          # 새로운 출력 디렉토리
    num_train_epochs=FINAL_TRAIN_EPOCHS,  # 결정된 최종 에포크 수
    per_device_train_batch_size=FINAL_BATCH_SIZE_TRAIN, # 기존 훈련 배치 크기
    gradient_accumulation_steps=FINAL_GRAD_ACCUM_STEPS, # 기존 값
    # --- 검증 관련 설정 제거/변경 ---
    eval_strategy="no",                   # 검증 안 함
    # --- 저장 관련 설정 ---
    save_strategy="epoch",                # 에포크마다 저장 (마지막 모델만 필요하면 "no" 또는 마지막 에포크만 저장)
    save_total_limit=1,                   # 마지막 체크포인트만 저장 (필요시 늘림)
    load_best_model_at_end=False,         # 최적 모델 로딩 안 함 (검증 없으므로)
    metric_for_best_model= None,
    # --- 기존 하이퍼파라미터 유지 ---
    warmup_steps=FINAL_WARMUP_STEPS,
    weight_decay=FINAL_WEIGHT_DECAY,
    learning_rate=FINAL_LEARNING_RATE,
    label_smoothing_factor=FINAL_LABEL_SMOOTHING,
    lr_scheduler_type=FINAL_LR_SCHEDULER,
    # --- 기타 설정 ---
    logging_steps=100,                    # 로그 간격 (데이터 양 고려하여 조정 가능)
    seed=RANDOM_STATE,                    # 재현성을 위한 시드 고정
    fp16=torch.cuda.is_available(),       # FP16 사용 (GPU 사용 시)
    dataloader_num_workers=2,             # 데이터 로더 워커 수
    remove_unused_columns=False,          # ReviewDataset에서 사용하는 컬럼 유지
    save_safetensors=True,                # Safetensors 형식으로 저장 권장
    logging_first_step=True,
    report_to="none",                     # 최종 재학습은 Wandb 로깅 안 함 (선택 사항)
    # push_to_hub=False, # 허깅페이스 허브 푸시 안 함
)
print("   TrainingArguments 설정 완료.")

# --- 5. 최종 Trainer 초기화 ---
#    - Focal Loss 사용 (CustomTrainerWithFocalLoss 클래스 필요)
#    - 검증 데이터셋, 메트릭 계산, 콜백 제거
print("\n🔧 최종 Trainer (CustomTrainerWithFocalLoss) 초기화 중...")
# CustomTrainerWithFocalLoss 클래스는 이전 셀(ID: eca0c60f)에 정의되어 있어야 합니다.
final_trainer = CustomTrainerWithFocalLoss(
    model=final_model,                  # 로드된 기반 모델
    args=final_training_args,           # 최종 훈련 설정
    train_dataset=full_train_dataset,   # 전체 학습 데이터셋
    eval_dataset=None,                  # 검증 데이터셋 없음
    tokenizer=final_tokenizer,          # DataCollator에 필요
    num_classes=NUM_CLASSES,            # 클래스 수
    focal_loss_alpha=FINAL_FOCAL_ALPHA, # 기존 Focal Loss alpha
    focal_loss_gamma=FINAL_FOCAL_GAMMA, # 기존 Focal Loss gamma
    data_collator=DataCollatorWithPadding(tokenizer=final_tokenizer), # 패딩 처리
    compute_metrics=None,               # 검증 안 하므로 메트릭 계산 불필요
    callbacks=None,                     # EarlyStopping 등 콜백 제거
)
print("   Trainer 초기화 완료.")

# --- 6. 전체 데이터로 재학습 실행 ---
print(f"\n💪 전체 데이터로 {FINAL_TRAIN_EPOCHS} 에포크 재학습 시작...")
try:
    train_result = final_trainer.train()
    print("   재학습 성공적으로 완료.")
    print(f"   총 훈련 시간: {train_result.metrics['train_runtime']:.2f}초")
    print(f"   최종 훈련 손실: {train_result.metrics['train_loss']:.4f}")
except KeyboardInterrupt:
    print("\n⚠️ 사용자에 의해 재학습이 중단되었습니다.")
except Exception as e:
    print(f"\n❌ 재학습 중 오류 발생: {e}")
    # 필요한 경우 오류 처리 로직 추가
    raise e

# --- 7. 최종 모델 저장 ---
print(f"\n💾 훈련 완료된 최종 모델 저장 중: {final_output_dir}")
try:
    # 기존 디렉토리가 있으면 삭제 (덮어쓰기 위해)
    if os.path.exists(final_output_dir):
        print(f"   기존 디렉토리 삭제: {final_output_dir}")
        shutil.rmtree(final_output_dir)

    final_trainer.save_model(final_output_dir) # 모델 가중치 및 설정 저장
    final_tokenizer.save_pretrained(final_output_dir) # 토크나이저 파일 저장
    print(f"   최종 모델 및 토크나이저 저장 완료: {final_output_dir}")

    # 저장된 파일 확인
    if os.path.exists(final_output_dir):
        saved_files = os.listdir(final_output_dir)
        print(f"   저장된 파일 목록: {saved_files}")

except Exception as e:
    print(f"❌ 최종 모델 저장 중 오류 발생: {e}")
    # 필요한 경우 오류 처리 로직 추가

# --- 8. 메모리 정리 ---
print("\n🧹 메모리 정리 중...")
del final_model
del final_tokenizer
del final_trainer
del full_train_dataset
del full_train_data
if 'train_result' in globals(): del train_result # 훈련 결과 객체도 삭제
if torch.cuda.is_available():
    torch.cuda.empty_cache()
    print("   GPU 캐시 비움 완료.")
print("   메모리 정리 완료.")

print("\n" + "="*60)
print("✅ 전체 데이터 재학습 및 최종 모델 저장 완료!")
print(f"   최종 모델은 '{final_output_dir}' 경로에 저장되었습니다.")
print("   추론(Inference) 시 이 경로의 모델을 사용하세요.")
print("="*60)
각 모델을 이전에 학습하는 train코드와 같은 방식을 공유하되, train, validation 데이터를 나누지 않고 전체 데이터를 사용해서 학습하는 코드를 구현했다. 일반적으로, 가장 성능이 좋았던 모델을 골라서, 다시 전체 데이터로 학습을 해서 제출한다고 한다. 하지만, 시간이 부족해서 다시 모델들을 재학습해보지는 못했다.
결과
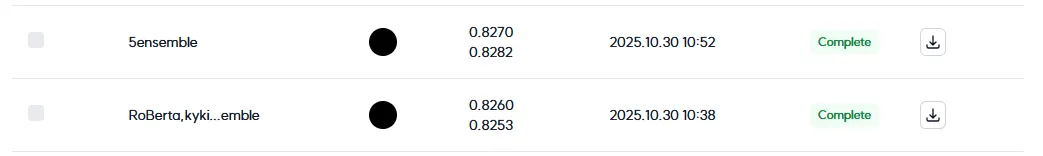
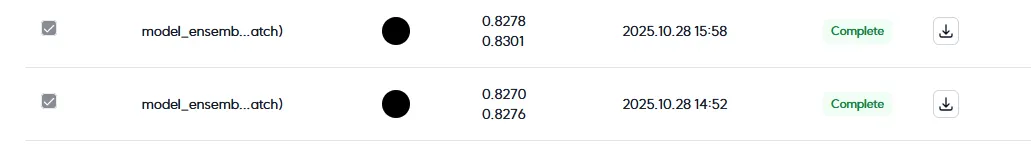
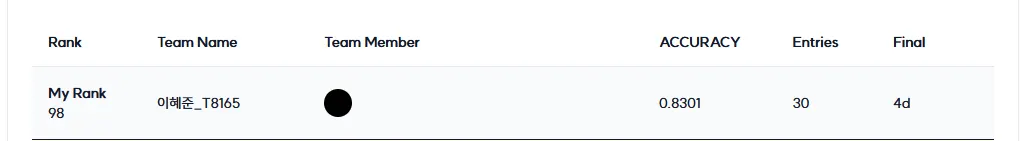
TAPT, FocalLoss의 $\alpha$가중치, SWA할 모델의 수등을 이전의 하이퍼파라미터 튜닝세팅과 다르게 해서인지, 이전에 BERT기반 3개모델을 앙상블했을때보다 성능이 비슷하거나 소폭하락했었다. 따라서 이전에 실험했던 모델들을 최종 제출했고, private score는 0.8301로 Final Leaderboard는 98위로 마무리했다. 첫 경진대회 참여라서 좋은 성과는 내지 못했지만 처음알고, 얻어가는것들이 많은 대회경험이었다.
하이퍼파라미터 튜닝을 하는 도중에 TAPT기법으로 모델성능을 향상시키는 방법을 알게되었고, BackTrainslation을 이용해서 효과적으로 데이터를 증강하거나, 전체 데이터셋을 이용해서 학습해서 성능을 향상해보는 시도들을 추가로 해보고싶었지만, 시간이 부족했었던것 같다. 모든 실험과 시도들을 해볼 수는 없다는것을 깨달았다. 가장 중요한것을 위주로 실험 우선순위를 결정해야하고, 중요한것부터 실험 자동화 스케줄러를 만들어서 24시간 GPU를 굴리는게 중요하다는것을 깨달았다.
- 하이퍼파라미터 튜닝은 가장 마지막과정에 시작해서 대회가 끝나기 직전까지 해야한다.
하이퍼파라미터 튜닝을 미리하면, TAPT적용이나, 데이터 증강등을 적용했을때, 최적의 하이퍼파라미터가 다시 달라지게 되므로 또 해야하는 불상사가 생긴다. EDA, FeatureEngineering등 모델링을 사전에 먼저 충분히 진행한 후 대회가 끝나기 직전까지 하이퍼파라미터 튜닝을 해야한다는것을 알게되었다.
- 우선 제일먼저 가능한 SOTA모델들을 실험해보고 사용할 모델을 고르자. 그리고 실험 우선순위를 먼저 정하자.
어떤모델을 사용할것인가를 가장 먼저 결정해야 한다. 이번 대회는 5개 모델을 한정적으로 사용헀기 떄문에, 간단했지만, 다른대회에서는 마지막에 앙상블할 모델들을 먼저 선택하고, 해당 모델들에 맞는 하이퍼파라미터 튜닝을 진행해야한다. 그리고 기간내에 모든 실험들을 해볼 수는 없다. 가장 중요한 실험부터 우선순위를 결정하고, 스케줄러를 이용해서 실험관리를 자동화해야한다. 하루에 10번의 제출을 할 수 있었지만, 많은 시도들을 해보지 못한것에 대한 아쉬움이 남는다.
Continue exploring
더 읽어보기
CTR을 예측할 수 있을리가 없잖아 무리무리!(무리가아니었다!?): nemotron persona
어떤 광고 배너가 잘될지는 결국 집행 비용을 써봐야 알 수 있었다. 배너를 많이 만들 수 있어도, 그중 무엇을 내보낼지 고르는 데는 여전히 돈이 들었다. 집행 전에 후보를 걸러낼 수 있을지 확인하려고 NVIDIA Nemotron Persona-Korea 데이터셋으...
카피 A/B 테스트와 밈으로 광고 성과를 끌어올리기
광고 배너를 자동으로 만들 수 있게 된 뒤에는 어떤 카피를 얹을지가 다음 과제였다. 성과가 높은 카피, 재밌는 카피에는 정해진 Ground Truth가 없었다. 여러 톤앤매너와 밈 RAG로 후보를 만들고 실제 광고 성과를 비교했다.
성과가 난 광고에서 다음 스토리를 찾는 위닝앵글 검색
초기 AX 제작은 좋아요 랭킹 순으로 스토리를 넓게 탐색하는 방식이었다. 이후에는 이미 성과가 난 광고에서 다음 후보를 찾는 경로를 만들었다. 다른 팀원이 만든 에이전트의 광고 성과 분석과 인사이트를 받아, 비슷한 소구점이나 이미지를 가진 새로운 스토리를 발굴하는...